Tracing the Roots: Trust Region Policy Optimization
This report examins the origins Trust Region Policy Optimization, which is of paramount importance in modern reinforcement learning.
anshu-arora-pranay-sharma
This report examins the origins Trust Region Policy Optimization, which is of paramount importance in modern reinforcement learning.
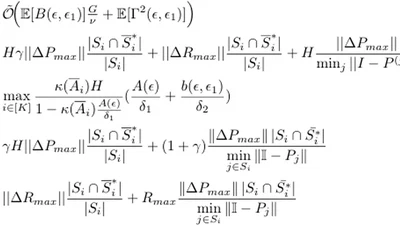
Analysed a clustering algorithm for TD(0) learning in federated reinforcement learning.
This is my exploratory project in Reinforcement Learning, where I have implemented common learning algorithms such as Q-learning, to play the mountain car game. I have also …