One-shot Clustering for Policy Evaluation in Federated TD Learning with LFA
Nov 7, 2025··
0 min read
Anshu Arora, Pranay Sharma, Avishek Ghosh
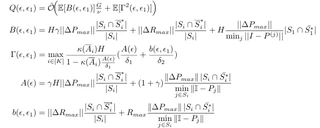
Abstract
In this work, we rigorously establish guarantees for achieving linear speed-up through collaboration in federated reinforcement learning. By introducing a new model of heterogeneity, we analyze how the perturbation of the virtual MDP relative to the TD(0) fixed point governs learning efficiency, and we quantify the effect of erroneous clustering on this perturbation. Our results demonstrate that, under mild assumptions, collaboration remains provably beneficial even in the presence of imperfect agent grouping.
Type
Publication
Unpublished